Large Language Model (LLM) Assessment
Simulating AI attacks and providing strategic roadmaps
AI Penetration Testing Services
Artificial Intelligence (AI) can be used to do many helpful things in everyday life but what happens when it’s prompted to perform a task that attacks security systems? TrustedSec is excited to offer an LLM Assessment service to fill in any gaps that might be overlooked in a traditional penetration test. By using a manual testing process, we provide strategic recommendations to home in on the foundation of the issue and correct the cause of exposure.
Methodology
TrustedSec's Large Language Model (LLM) Assessment is a primarily manual approach targeting the technical security challenges presented by LLMs. The assessment focuses on LLM interactions with web application and web API components.
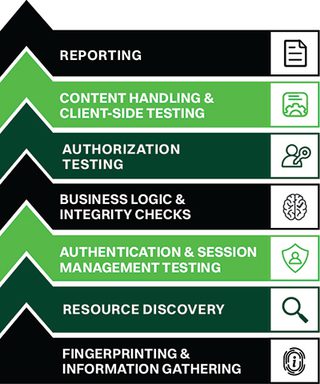
TrustedSec's approach is to gain an understanding of the attack surface. Manual investigation of the application is performed to identify what inputs the LLM or machine learning (ML) system relies on, including training data, prompts, and reference resource inclusion. TrustedSec continues the discovery process by investigating API interaction and in-band and OOB response behavior and then searches for exposures related to connected business logic and information disclosures. The manual testing process is informed by NIST AI 600-1, and the OWASP LLM Top 10 typically includes, but is not limited to, the following:
- Data poisoning or attempts to inject malicious data into the training or retraining to attempt to control model outputs
- Model inversion or use of response correlation to derive sensitive data that may have been present in system prompt inputs or training data
- Discovery of confidentiality violations through adversarial prompting
- Attempting to trigger authorization violations through adversarial prompting, including resource manipulation, targeted attacks leveraging excessive agency, and API integration weaknesses
- Indirect prompt and inline markup attacks, which attempt to insert attacker-controlled tokens via included resources that will be treated as part of a victim's prompt inputs
- Evasion attacks, sometimes referred to as jailbreaks, that include the crafting of inputs specifically designed to bypass model restrictions, such as generating negative content about first-party products and services
- Request forgery and related web technology attacks designed to identify weaknesses in API integrations
Strategic Recommendations
Organizations typically focus efforts on the Technical Findings from an LLM Assessment. Although Technical Findings are important, fixing the root cause of the issue is a crucial outcome of the assessment. If the root cause of an exposure can be corrected, the longer-term security program will be significantly more successful than if only the Technical Findings are remediated. TrustedSec outlines the root causes in the form of Strategic Recommendations. Where applicable, the Strategic Recommendations outline long, mid, and short-term actions to provide a roadmap for remediating the underlying root cause.
Get Started with an LLM Assessment
Ready to see how your defenses hold up against Artificial Intelligence? Let's talk.

Our research on Artificial Intelligence
TrustedSec experts provide up-to-date information, tools, and tips on the latest in AI.

Navigating the Initial AI Best-Practice Framework Offerings
Discover the current landscape of AI best-practice frameworks, what each major framework offers, where it works well, where it falls short, and how to decide…
TrustedSec Joins the OpenAI Daybreak Defense Network
TrustedSec is proud to announce its partnership with OpenAI’s Daybreak Defense Network. Our Founder and CEO David Kennedy explains what it all entails.
HashcatRosetta: Reading the Rosetta Stone of Password Cracking
Meet HashcatRosetta—the Hashcat rule decoder you didn't know you needed. In Part 2 of this blog series, we go through how it translates, analyzes, and…
Securing Cloud AI: Real-World Scenarios in AWS, Azure, and GCP
Join our cloud security team as they dig into real-world exposures tied to popular AI-based services. Learn how to find the gaps to make AI more secure for…
Security Noise - The Agent Will Handle It
Episode 9.3

What's New in hate_crack Since 2.0
You thought you knew hate_crack 👀 Well, version 2.0 changed that. In Part 1 of this latest blog series, we go through 13 new attack methods, menu…
LLMHaxor Update
Most LLM testing tools require setup, paid access, or internet; LLMHaxor requires none of that. In this blog, we walk through the latest update, including a…
We've Seen This Movie: The OT/IT Technology Divide
Manufacturing knows what happens when IT and OT divide; AI governance is an unexpected chance to do it differently. In this blog, we walk through a unified…

AI Offense is Not Noclip Mode
AI doesn't let attackers walk through walls, but it makes finding the cracks more efficient. In this blog, we cut through the hype and explain what AI-driven…
AI Directives and AI Strategy Development
The hardest part of AI adoption isn't the tech, it's the strategy. In this blog, we outline a practical framework covering governance, risk classification,…